
How Can SLED Organizations Accelerate Incident Response?
Reducing incident response times can help limit operational disruption and prevent a security incident from escalating. We recommend starting with a documented incident response plan that assigns clear roles to security, IT, legal, communications, and executive stakeholders.
The latest version of NIST SP 800-61 recommends incorporating incident response throughout an organization’s broader cybersecurity risk-management activities. This approach helps teams prepare for incidents and improve the efficiency of detection, response, and recovery.
Continuous monitoring can also help teams identify suspicious activity earlier. Risk-based alert prioritization allows analysts to focus on threats with the greatest potential impact, while automation can support routine activities such as alert enrichment, evidence collection, and initial containment.
Cross-functional training is equally important. Incident responders, IT staff, leadership, legal teams, and communications personnel should understand their respective responsibilities before an incident occurs. Regular tabletop exercises can help organizations test escalation paths, communications procedures, and recovery plans. CISA provides customizable tabletop exercise resources that organizations can use to evaluate and strengthen their readiness.
Information-sharing partnerships can provide additional insight into emerging threats. SLED organizations may benefit from participating in relevant information-sharing communities, including the Multi-State Information Sharing and Analysis Center, which supports U.S. state, local, tribal, and territorial government organizations.
What Should SLED Organizations Measure to Improve Incident Response?
SLED organizations should measure how quickly incidents are detected, acknowledged, contained, and resolved. Tracking each stage separately helps teams identify where delays occur and determine whether improvements to technology, staffing, or procedures are producing better outcomes.
Important incident response metrics include:
- Mean Time to Detect (MTTD): How long it takes to identify suspicious or malicious activity after it begins. Continuous monitoring, better telemetry, and contextual detection can help reduce this interval.
- Mean Time to Acknowledge (MTTA): How quickly the responsible team reviews and accepts ownership of a detected incident. Long acknowledgment times may indicate unclear escalation procedures, excessive alert volume, or insufficient after-hours coverage.
- Mean Time to Contain (MTTC): How long it takes to prevent a confirmed threat from spreading or causing further harm. For SLED organizations, containment procedures should account for the operational consequences of disconnecting systems that support public safety, education, utilities, or constituent services.
- Mean Time to Respond or Remediate (MTTR): How quickly the organization completes the approved response actions needed to address an incident. Because “MTTR” can also refer to recovery or resolution, organizations should clearly define what the metric means in their reporting.
- Recovery Time Objective (RTO): The maximum acceptable amount of time a critical service can remain unavailable. RTOs should be established according to operational impact rather than applied uniformly across every system.
- Recovery Point Objective (RPO): The maximum acceptable amount of data loss, measured in time. RPOs help determine how frequently systems must be backed up and which services require the strongest recovery capabilities.
Organizations should establish a baseline for each metric and monitor trends over time rather than relying on a single organization-wide average. Results should also be segmented by incident severity, system type, department, and whether the response was completed through automation or analyst action. A phishing investigation and an attack affecting emergency communications should not be evaluated as equivalent events.
These measurements help leaders identify whether delays originate in detection, escalation, decision-making, containment, or recovery. They also provide a practical way to evaluate tabletop exercises, staffing changes, managed security services, and new technology investments.
How Can Organizations Improve Cybersecurity Maturity With Limited Resources?
Cybersecurity maturity is not determined solely by the size of an organization’s budget or security team. Organizations can make measurable progress by identifying their most important systems, understanding their greatest risks, and prioritizing foundational controls.
We recommend using the NIST Cybersecurity Framework 2.0 to organize cybersecurity activities around six functions: Govern, Identify, Protect, Detect, Respond, and Recover. Teams do not need to implement every improvement simultaneously. They can begin with the controls that address their most significant risks and expand their programs over time.
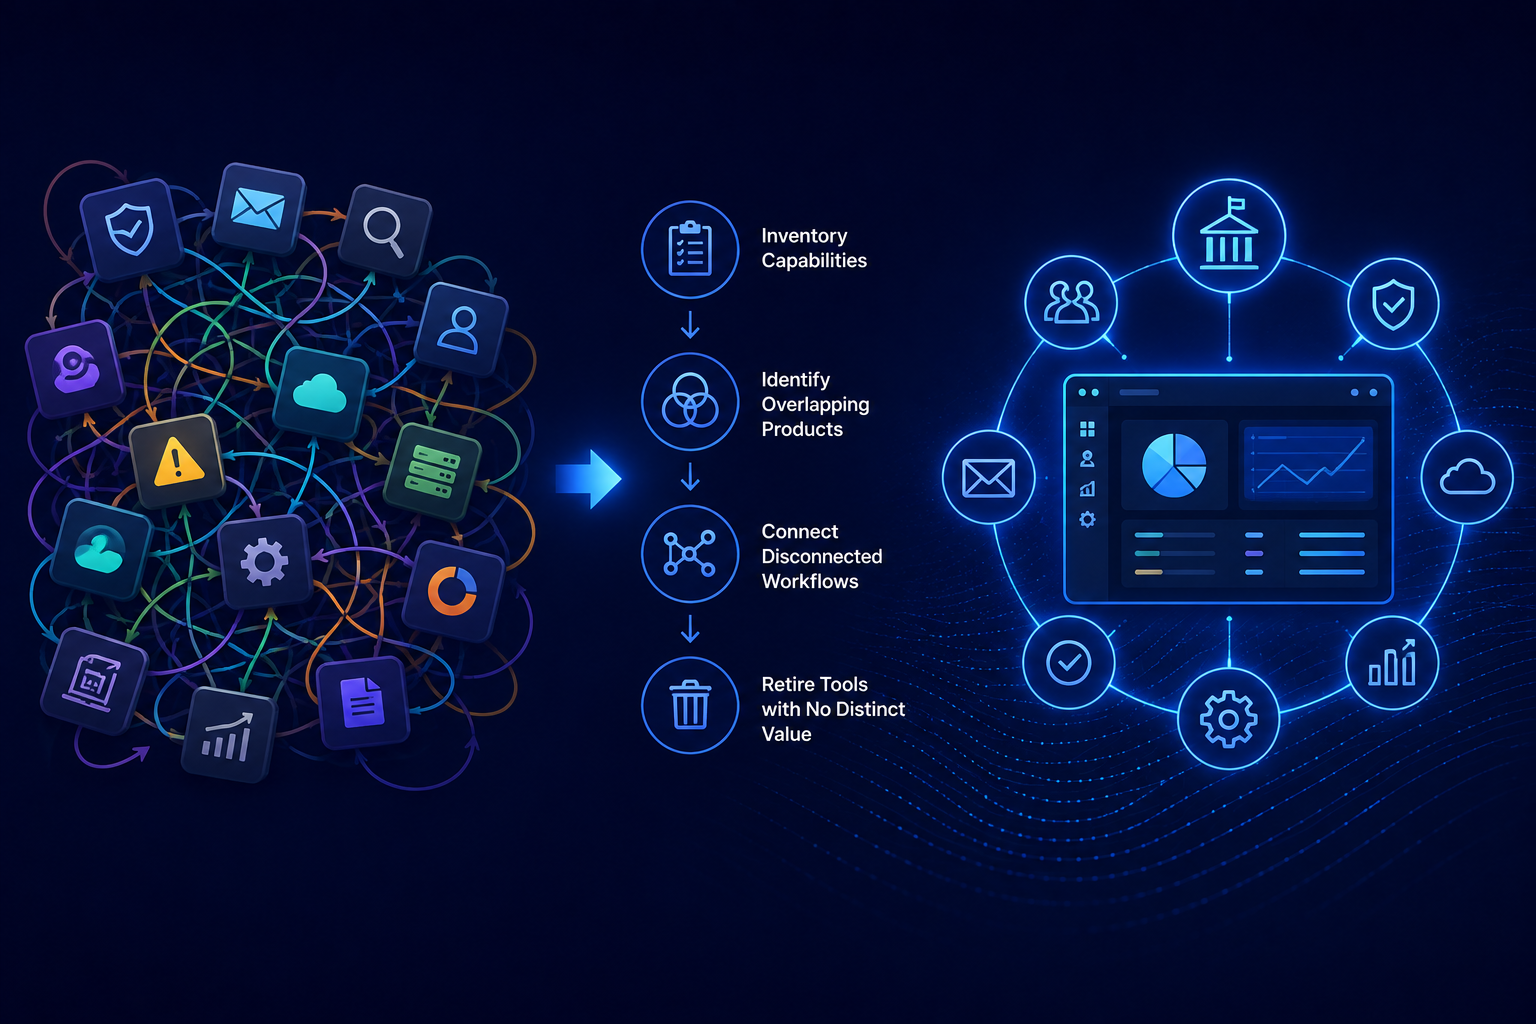
Tool consolidation may also help reduce operational complexity. When analysts must investigate disconnected alerts across multiple systems, incident response can become slower and more difficult. Integrated monitoring and response processes can provide analysts with more context while reducing unnecessary manual work.
Organizations can also use managed detection and response services to supplement internal capabilities. MDR may provide continuous monitoring, incident investigation, and response support without requiring an organization to staff every security function internally.
Employee education remains an important part of cybersecurity maturity. Training should address phishing, account security, data handling, and reporting procedures. Organizations should also review their policies, risks, and response plans regularly as their technology and threat environments change.
SLED Incident Response Best Practices
SLED organizations often operate across distributed environments with limited personnel, multiple stakeholder groups, and complex regulatory responsibilities. The following practices can help create a more efficient and coordinated response process.
1. Implement a Clear Incident Response Plan
Develop an incident response plan aligned with NIST SP 800-61 Revision 3. The plan should document roles, detection and reporting procedures, escalation paths, communications responsibilities, containment processes, and recovery priorities.
Review the plan after exercises, significant organizational changes, and actual incidents.
2. Enable Continuous Detection and Prioritization
Monitor endpoints, networks, identities, cloud environments, and other critical systems for suspicious activity. Use contextual information and risk-based prioritization to distinguish urgent threats from lower-risk events.
Reducing unnecessary alert noise helps analysts dedicate more time to incidents that could materially affect operations.
3. Establish Cross-Department Coordination
Include representatives from security, IT, legal, communications, operations, and executive leadership in incident response planning. Each stakeholder should understand when they will be involved, what decisions they are authorized to make, and how information will be shared.
4. Use Automation Carefully
Automate repetitive and well-defined activities such as alert enrichment, evidence collection, case creation, and approved containment actions. Organizations should establish appropriate oversight and safeguards, particularly when an automated action could interrupt critical public services.
5. Conduct Regular Training and Exercises
Use tabletop exercises to test responsibilities, escalation paths, decision-making, communications, and recovery procedures. After each exercise, document identified gaps and assign responsibility for corrective actions.
Organizations can use CISA’s Tabletop Exercise Packages to help structure these exercises.
6. Participate in Information-Sharing Communities
Relevant ISACs, government cybersecurity coalitions, and trusted public-private partnerships can help SLED organizations learn about emerging threats and defensive practices. Participation should complement, rather than replace, an organization’s internal monitoring and response capabilities.
How AgileBlue Helps Support Incident Response
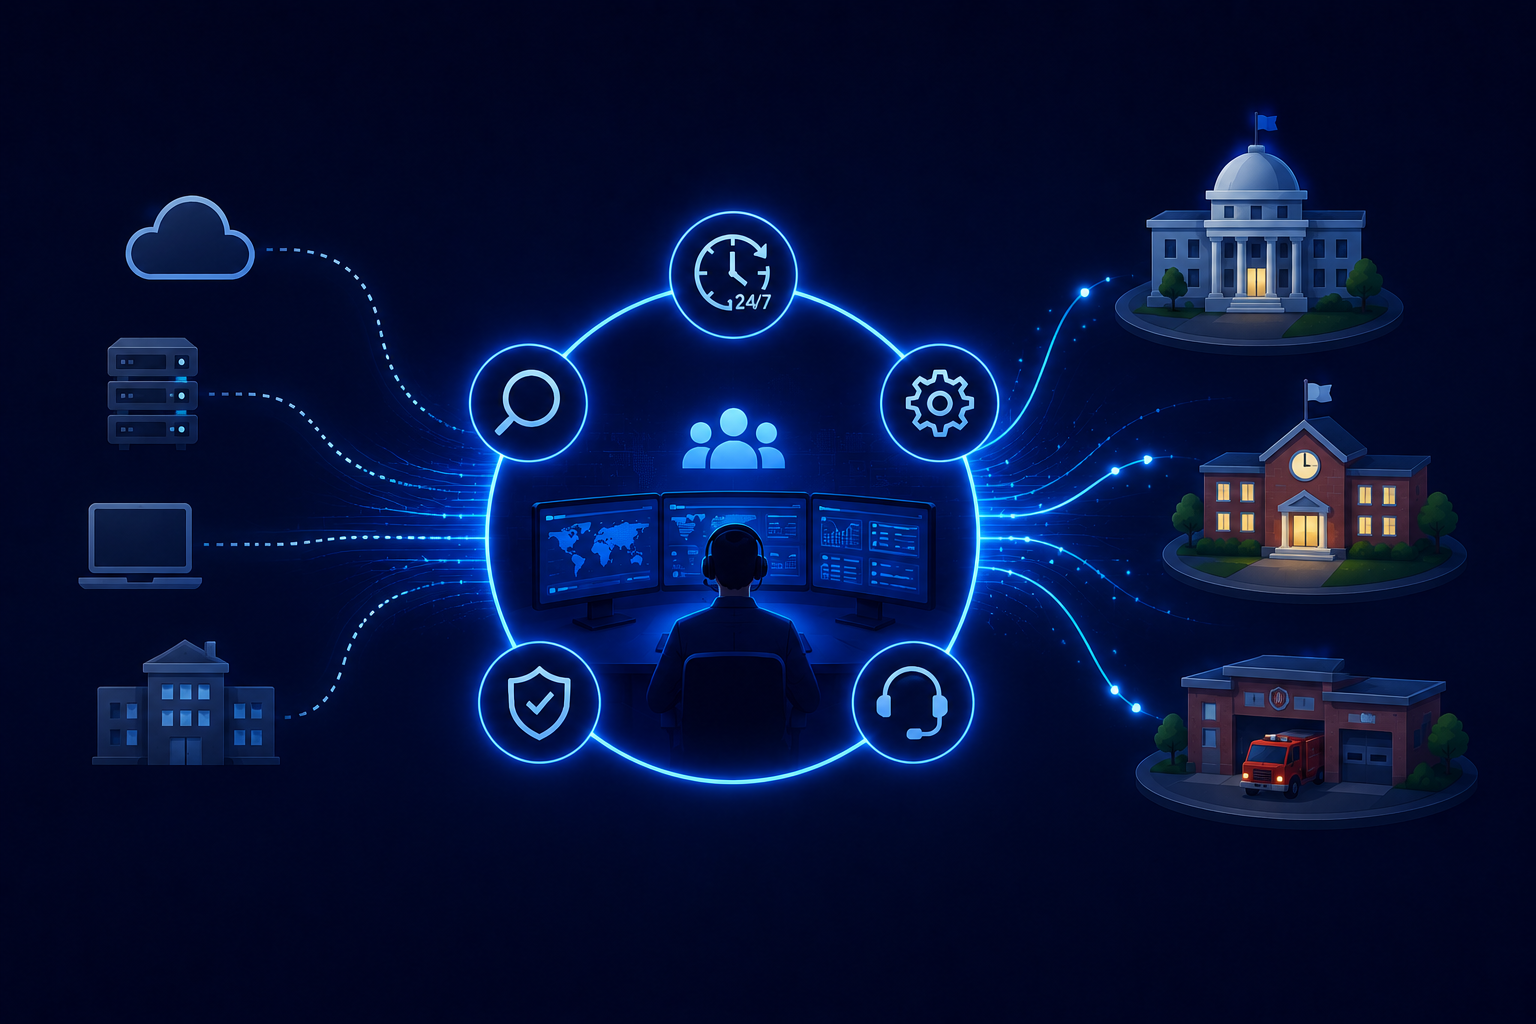
AgileBlue helps SLED organizations reduce the time between suspicious activity, confirmed detection, and containment. Sapphire AI continuously correlates activity across the environment, investigates potential threats, closes benign cases, and initiates approved response actions according to each customer’s preferences. When an incident requires human judgment, AgileBlue’s 24/7 U.S.-based SOC analysts respond based on the organization’s established procedures.
This model gives lean teams continuous coverage without removing customer control. Agencies can determine which actions Sapphire AI may execute autonomously, which require analyst involvement, and which must be approved internally, an important distinction when containment could affect public safety, classroom operations, utilities, or other essential services.
AgileBlue also gives security leaders visibility into Mean Time to Detect, autonomous Mean Time to Respond, and analyst Mean Time to Respond. These measurements help organizations establish a performance baseline, identify response bottlenecks, and demonstrate whether process and technology improvements are producing faster outcomes.
Technology does not replace a documented incident response plan, trained personnel, or tested recovery procedures. It helps those plans operate faster and more consistently when an incident occurs.
Organizations can also learn more about why incident response is an essential part of cybersecurity strategy and explore our incident readiness services.
Strengthen Your Incident Response Readiness
Organizations seeking faster and more coordinated incident response should begin by assessing their current plans, monitoring capabilities, staffing, and decision-making processes. From there, they can prioritize practical improvements and determine where external expertise or automation could strengthen internal capabilities.
Contact our team to discuss your current incident response program and identify areas for improvement.
Frequently Asked Questions
Q: What is the average incident response time for SLED organizations?
A: There is no single, authoritative average that applies to every SLED organization. Response times vary based on the severity of incident, available personnel, monitoring coverage, escalation procedures, and the organization’s technical environment. Instead of relying on a broad industry average, organizations should establish baselines for Mean Time to Detect, Acknowledge, Contain, and Respond, then track improvement by incident type and severity.
Q: Which incident response metrics should SLED organizations track?
A: SLED organizations should track Mean Time to Detect (MTTD), Mean Time to Acknowledge (MTTA), Mean Time to Contain (MTTC), and Mean Time to Respond or Remediate (MTTR). They should also establish Recovery Time Objectives and Recovery Point Objectives for critical services. Because organizations use “MTTR” differently, the intended measurement should be clearly defined in reports.
Q: How can a small SLED IT team provide 24/7 incident response coverage?
A: Small teams can combine continuous monitoring, risk-based alert prioritization, approved automation, documented escalation procedures, and external MDR support. The provider’s responsibilities should be clearly defined, including which actions can be performed automatically, when analysts intervene, when the internal team is contacted, and who can authorize containment that may affect critical services.
Q: Which frameworks can help organizations develop incident response plans?
A: NIST SP 800-61 Revision 3 provides current incident response recommendations aligned with the NIST Cybersecurity Framework 2.0. Together, they help organizations incorporate preparation, detection, response, and recovery into broader cybersecurity risk management.
Q: Why is cross-agency collaboration important?
A: Collaboration can improve situational awareness and give organizations access to threat information, shared expertise, and response resources. However, each organization still needs its own documented and tested incident response procedures.